Anthropic Launches Claude Fable 5.2 and Mythos 5.2: 20% Cheaper, Up to 30% Faster, and a Top FrontierCode Score
Anthropic has released Claude Fable 5.2 and Mythos 5.2, with gains in coding, reasoning, and vision, output up to 30% faster, and a lower price of $8 and $40 per million tokens. Fable 5.2 is available today on all platforms, while Mythos 5.2 is limited to vetted organizations.
By Nattapon YongpaiboonCo-founder, Claude Thailand Community
Anthropic released Claude Fable 5.2 and Claude Mythos 5.2 on November 9, 2026.
The two are the same underlying model with different safeguards:
- Fable 5.2 has stronger cybersecurity and biology safeguards and is available to everyone
- Mythos 5.2 has fewer safeguards and is limited to vetted organizations
Anthropic positions both for the most ambitious, open-ended technical work. For most coding and knowledge tasks, it recommends starting with Claude Opus 5.5, then moving up to Fable or down to Sonnet 5.5 or Haiku 5.5 as needed.
What’s new
- Smarter: gains in coding, reasoning, and vision, and testers say it explains its work more clearly
- Faster: output is up to 30% faster than Fable 5.1 and Mythos 5.1
- More token-efficient: at Medium effort, the default in the Claude apps and Claude Code, Fable 5.2 uses fewer tokens than Fable 5.1
- Works with smaller models: Fable 5.2 can act as an Advisor to smaller models, or as an Orchestrator that hands simpler tasks to other models
Pricing
| Input | Output | |
|---|---|---|
| Standard | $8 per million tokens | $40 per million tokens |
| Fast mode (up to 2.5x faster token generation) | $16 per million tokens | $80 per million tokens |
The standard price is about 20% lower than Fable 5.1, which was $10 and $50 per million tokens.
Higher scores for less money
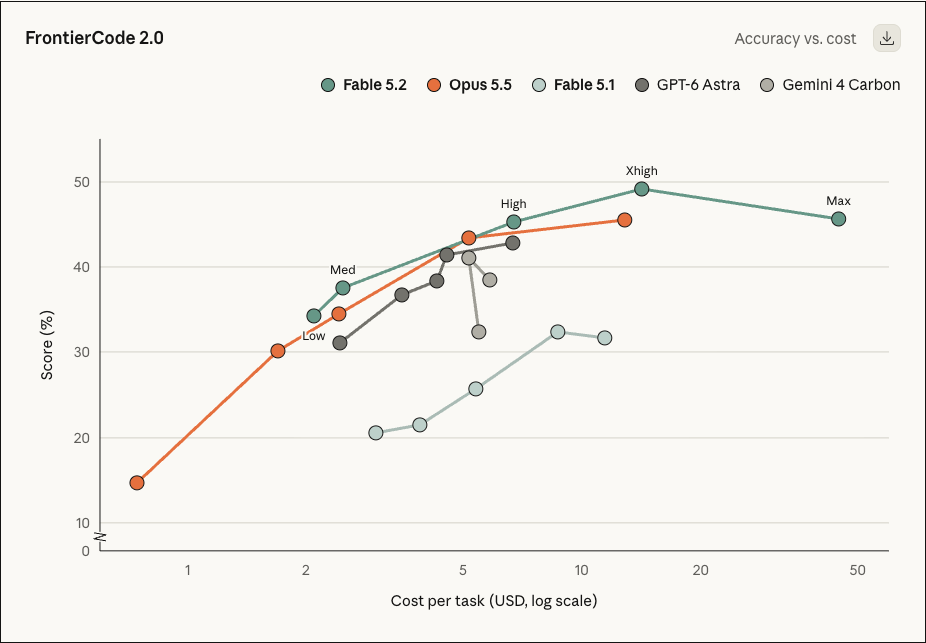
FrontierCode 2.0 measures how ready a model’s code changes are to merge, as scored by open-source maintainers.
- At High effort, Fable 5.2 scores 45.3%, about level with Opus 5.5’s best (45.5%) at roughly half the cost per task, and ahead of GPT-6 Astra’s best (42.8%) at about the same cost
- At Xhigh effort, Fable 5.2 reaches 49.1%, the highest of any released model Anthropic tested
The same pattern shows up elsewhere:
- HLE: at Low effort, it matches Opus 5.5’s top score at under one-tenth of the cost
- Chartography: at Medium effort, it scores 66.4%, above Opus 5.5 at Max (64.4%), at under one-tenth of the cost
Benchmarks against other models
Scores are at each model’s highest effort unless noted.
| Benchmark | Fable 5.2 | Fable 5.1 | Opus 5.5 | GPT-6 Astra | Gemini 4 Carbon |
|---|---|---|---|---|---|
| FrontierCode 2.0 | 49.1% | 32.4% | 45.5% | 42.8% | 41.1% |
| FrontierSWE v2 | 69.9% | 56.3% | 62.3% | 65.5% | 61.2% |
| Terminal-Bench-Science 0.1 | 74.6% | 52.6% | 58.7% | 68.1% | 64.8% |
| AutomationBench | 51.4% | 31.4% | 42.5% | 41.4% | 53.9% |
| OSWorld 2.1 | 89.3% | 83.5% | 87.2% | 79.5% | 81.5% |
| Remote Labor Index (High) | 41.3% | 17.9% | 21.3% | 20.8% | - |
| Humanity’s Last Exam (with tools) | 74.2% | 65.6% | 67.7% | 57.2% | - |
| Chartography (no tools) | 73.4% | 44.8% | 64.4% | 71.0% | 72.5% |
Fable 5.2 leads almost every benchmark in the table. The exception is AutomationBench, where Gemini 4 Carbon scores higher.
What Anthropic says it has done
- Coding: Claude now writes over 90% of the changes merged into Anthropic’s core codebase. One engineer used Fable 5.2 to design a prototype operating system that boots on a laptop, coordinating over 1,000 subagents for eight days
- Mathematics: a team of about 1,000 Fable 5.2 agents formalized Fermat’s Last Theorem in 30 hours. Anthropic’s first formalization took 11 days
- Hardware: Fable 5.2 designed three working electronic devices that worked without electrical modifications
- Cybersecurity: Mythos 5.2 scores 89.6% on CVE Rediscovery, finding about 10.2% more vulnerabilities than Opus 5.5
Where it’s available
- Fable 5.2 is available today on all platforms, including Amazon Web Services, Google Cloud, and Microsoft Azure. The API model ID is
claude-fable-5-2 - Fable on subscription plans: Pro and standard Team seats can use Fable for up to half of their weekly limit. Eligible paid plans get one to three Fable resets, based on how long you have subscribed
- Fast mode is available in Claude Code, the Claude Platform, Google Cloud, and Microsoft Foundry
- Mythos 5.2 is limited to organizations in the Cyber Verification Program or the Life Sciences Verification Program. Claude Enterprise customers can use Mythos 5.2 for code scanning through Claude Security
Safety
- Fewer blocked queries: Fable 5.2 blocks about 55% fewer queries than Fable 5.1. Blocked cyber or biology queries fall back to an earlier model
- Low risk assessment: Anthropic considers the risk of high-stakes misalignment low. External testers included the UK AI Security Institute and METR
- Far fewer sandbox escapes: in a dedicated test, Mythos 5.2 used credentials or files outside its sandbox in 3.1% of scenarios, down from 21% for Mythos 5.1
Full details are in the Claude Fable 5.2 and Mythos 5.2 System Card.
See also the launch of Claude Opus 5.5.
Get it by email
New articles, Claude updates and community event announcements. Sent occasionally, never often enough to annoy you.
The newsletter is written in Thai